MeshAnything: Artist-Created Mesh Generation with Autoregressive Transformers
Turns any 3D representation into the clean, low-poly meshes artists actually use.
During my Ph.D., I explored how AI can understand the physical world through space, shape, and motion.
Turns any 3D representation into the clean, low-poly meshes artists actually use.
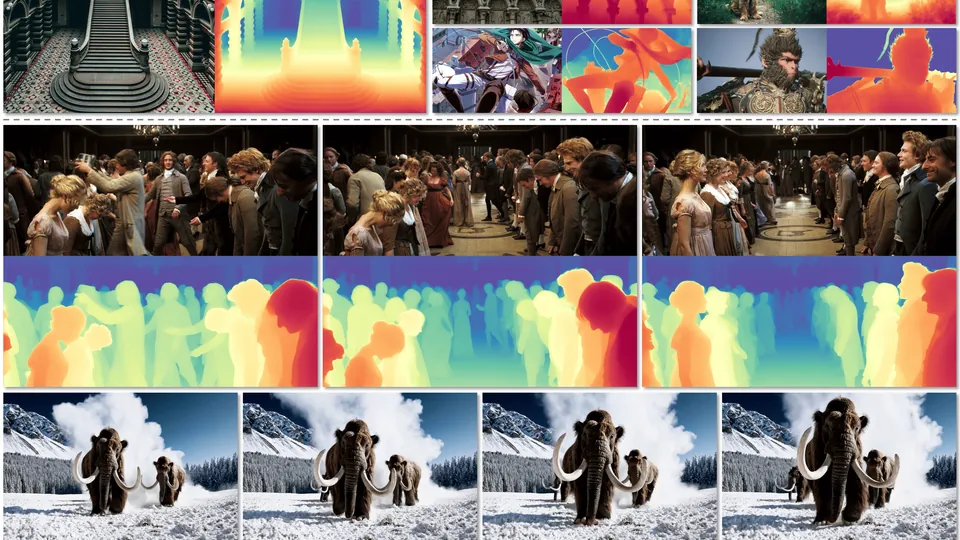
Consistent video depth estimation, trained on 40,000 clips captured from game engines.
Fine-tunes an LLM to generate human motion from text, poses, or both.
Self-supervised pre-training for driving perception through 3D volumetric rendering.
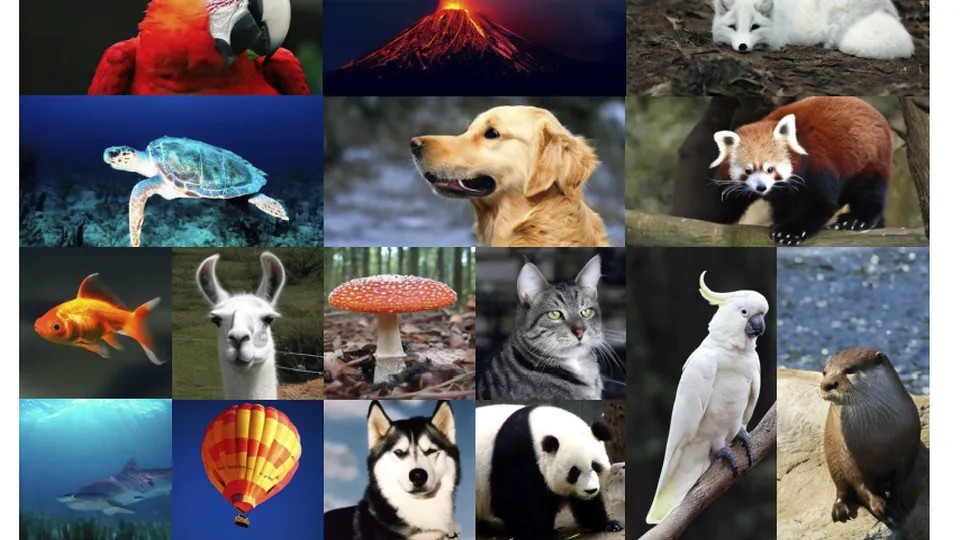
A diffusion transformer that generates images at any resolution and aspect ratio.
Recovers fine, detailed surfaces from images with a two-stage SDF approach.
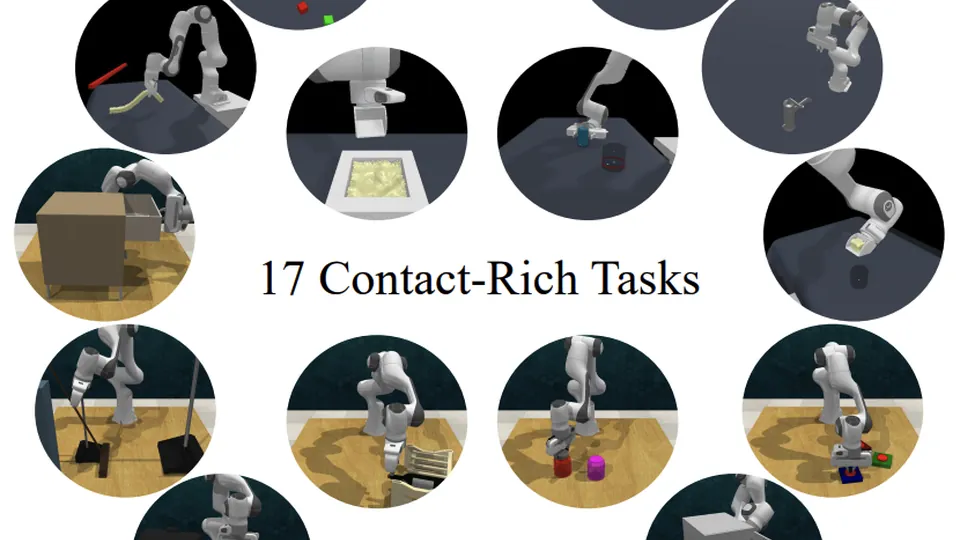
A benchmark of 125 tasks showing how RGB, RGB-D, and point clouds change what robots learn.
Generates 3D Gaussians from text in about 7 seconds with a structured volumetric representation.
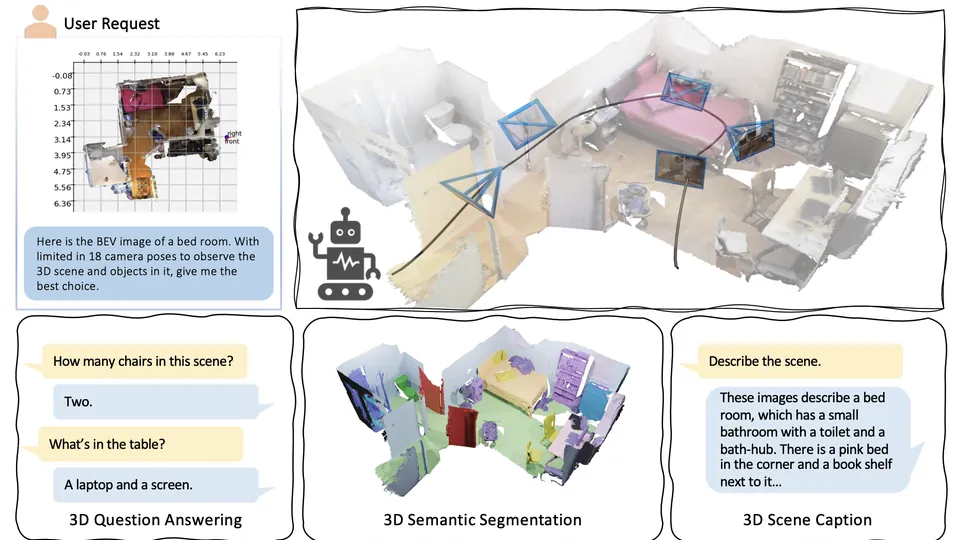
A vision-language agent that understands 3D scenes by choosing which views to look at.
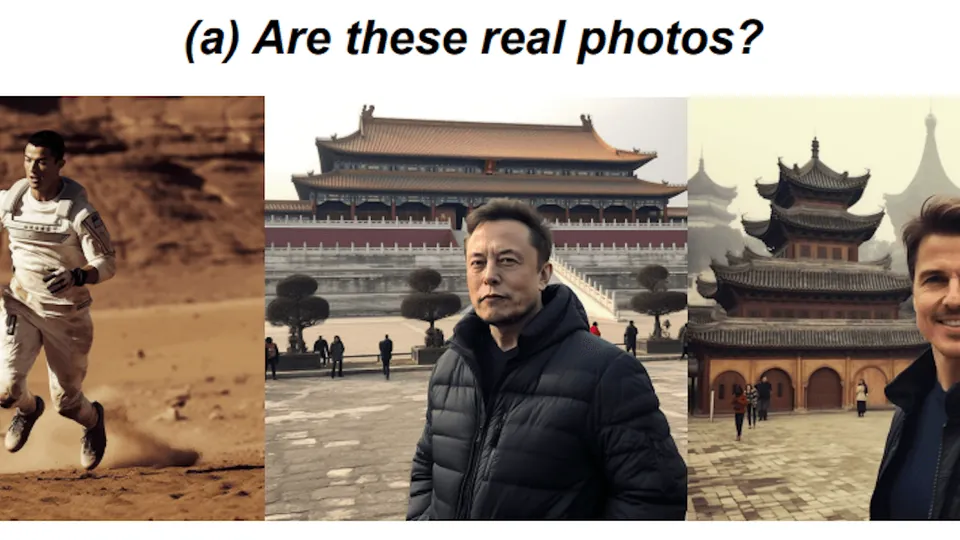
People misjudge whether a photo is real or AI-generated 38.7% of the time.
Learns point cloud features by rendering them back into realistic images.
Uses the moving hand as a free multi-view rig to reconstruct the object it holds.
Estimates object pose from a single video scan, even for low-texture objects.
An open-source toolbox for markerless human motion capture from one or more cameras.